Transcripts with speaker separation
Digitale Profis presents Voxtral 3 as Mistral’s renewed family of speech models. It includes transcription for recordings, the ability to distinguish speakers, a realtime variant and a separate model for speech output. These are different parts of the same family rather than a single transcription feature. The channel describes speech recognition across roughly 50 languages, alongside tools for bringing spoken conversations into software workflows.
Giving recognition useful context
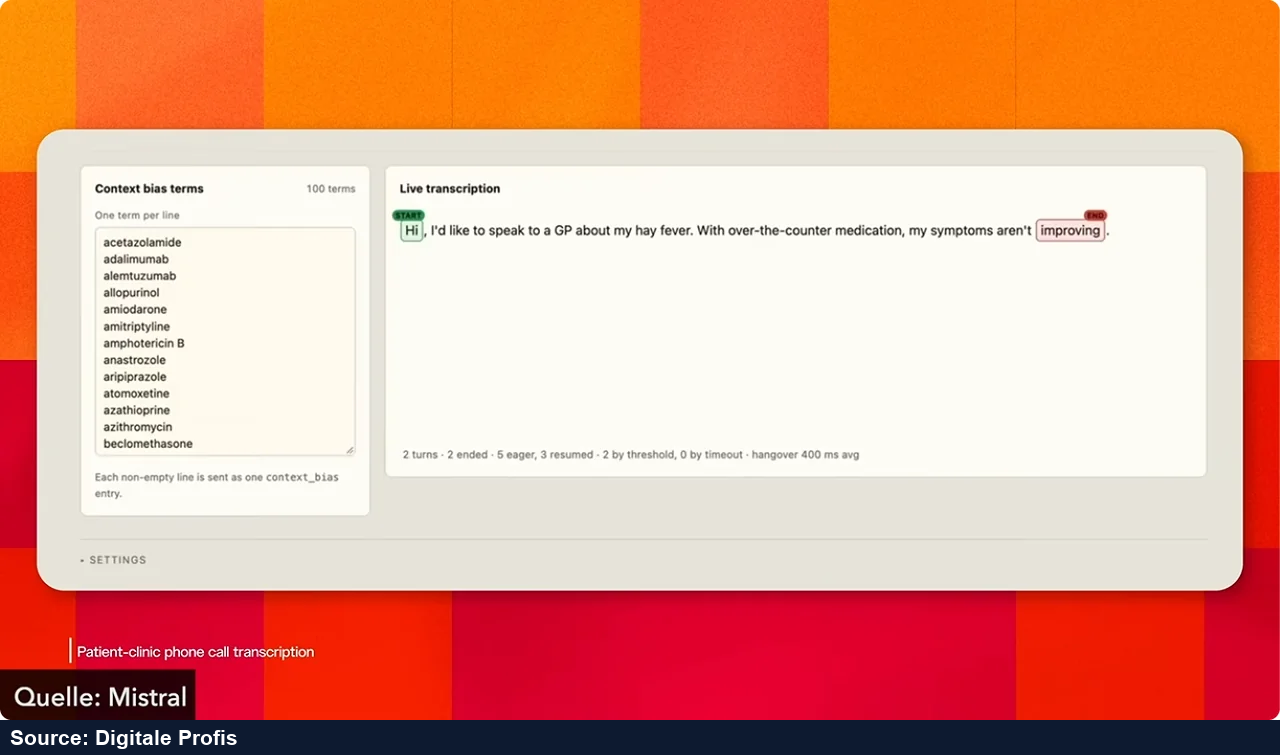
Relevant terms can be supplied before an audio task. Product names and specialist vocabulary can therefore be included as context when they are likely to appear in the conversation. The feature addresses a practical difficulty of transcription: a general conversation and one containing unfamiliar names do not present the same recognition task. Alongside transcription, Mistral supplies an SDK for developers building their own voice agents.
From a conversation to a tool
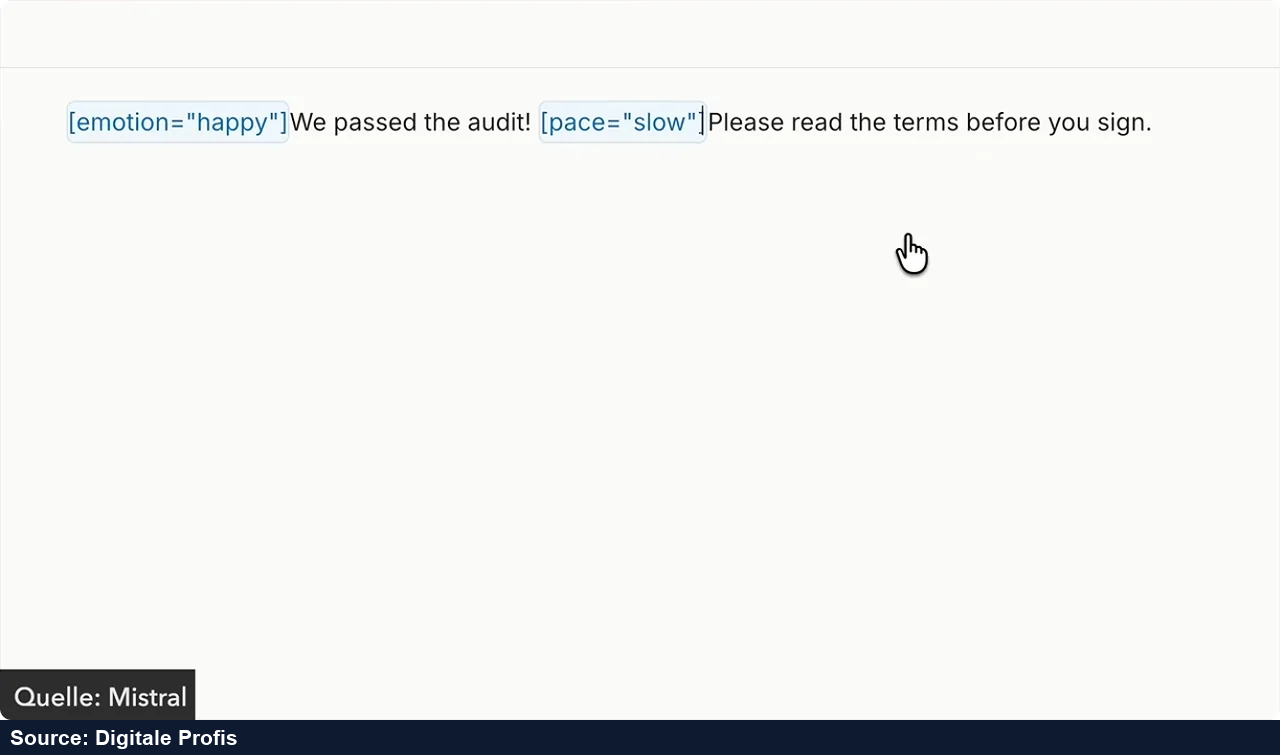
The SDK connects listening and speaking with a language model and software tools. The channel illustrates this with a possible telephone assistant that checks an available appointment during a call and prepares a booking. The example combines a spoken request with a lookup in connected software and a prepared action. Mistral offers European-hosted API access and deployment on an organisation’s own infrastructure, giving companies a choice of processing environment.

