

Being good at a research benchmark is not the same as choosing the next great scientific question. AI Explained’s October 2026 discussion connects mathematical manuscripts with TasteVal, a test of experimental research decisions. The most useful lesson is to ask exactly what was measured before declaring that research has been automated.
We read the complete video captions and checked the primary research sources on 1 November 2026. Mathematical correctness, benchmark performance and predictions about recursive self-improvement are treated separately. Recursive self-improvement means AI helping improve the systems that produce later AI.
Manuscripts are not all equally verified
OpenAI’s repository lists 721 manuscripts in 373 families, with about 42% of top-line results formalized. It describes the collection as raw research data and warns that unformalized results can contain issues. A family is not the same unit as a file, a theorem or an independently accepted breakthrough.
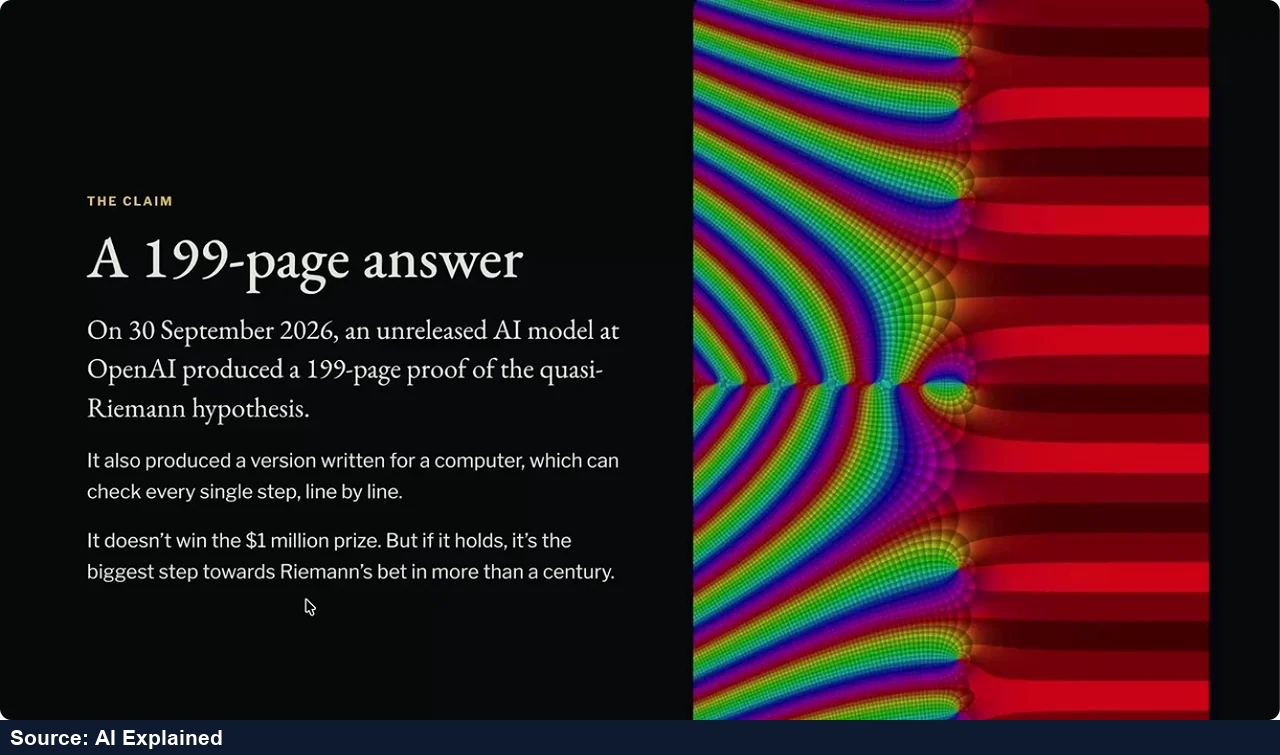
The video highlights a proposed advance around the Riemann zeta function. We have not checked the underlying proof and do not label the full Riemann hypothesis solved. A related result, a proposed proof, a machine-checked formalization and broad mathematical acceptance are distinct claims. Readers should follow the specific manuscript and its revision history rather than infer correctness from the collection’s size.
The 6 October announcement was updated on 15 October with $5 million for a Simons Foundation initiative supporting examination of AI-produced mathematics. That update came after the video. It supports further investigation, not automatic certification of every manuscript.
Who made the criticism?
A 7 October post on Terence Tao’s blog explicitly identifies the text as a guest statement by the Association for Human Mathematics. Its criticism of publication practices must be attributed to that group, not silently converted into Tao’s personal verdict or proof that each result is false.
Scientific review has more than one axis. A technically correct proof may still be difficult to explain, poorly credited or costly to check. A criticism of the release process does not alone settle correctness; a formal check does not alone settle those broader concerns. Our earlier ETH article covers another claimed result. This article focuses on research measurement, not a repeat of that announcement.
What TasteVal actually tests
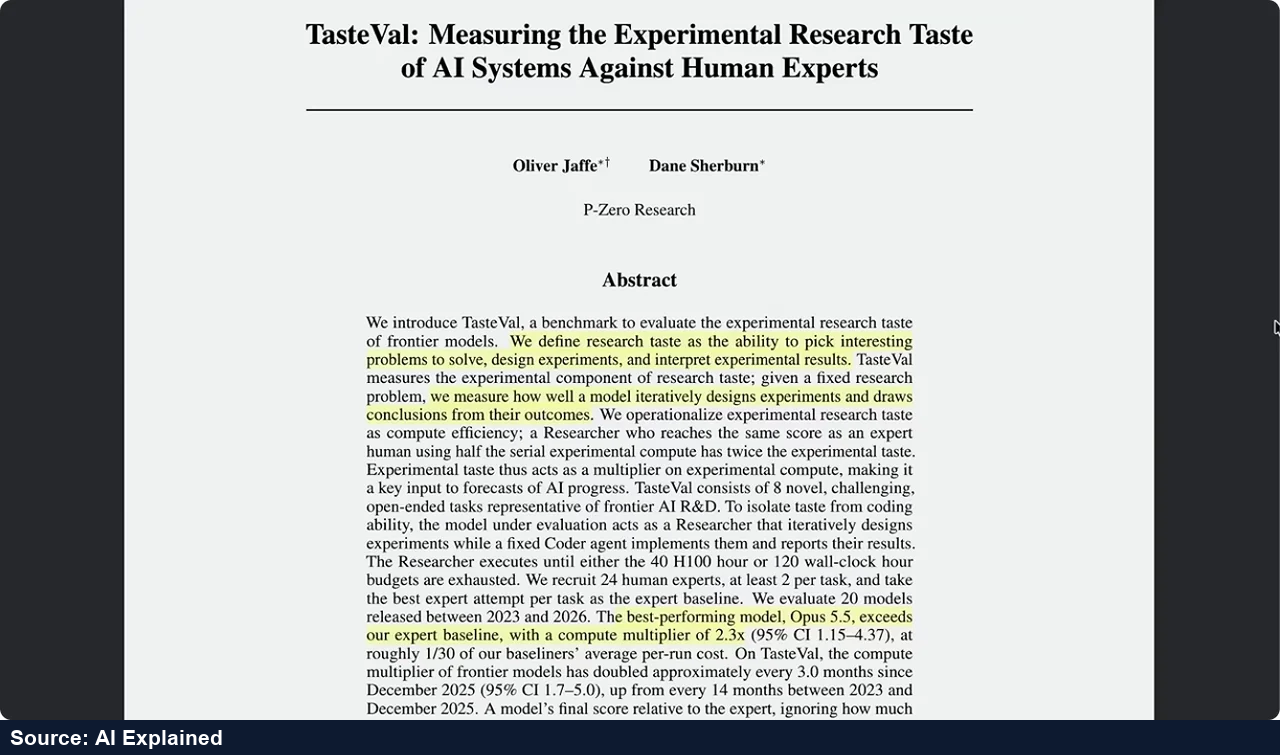
The TasteVal paper uses eight tasks, a fixed coding agent and 24 human experts. Runs stop at 40 H100 GPU-hours or 120 elapsed hours. Opus 5.5’s reported compute multiplier is 2.3×, with a 95% confidence interval of 1.15–4.37. This is compute efficiency relative to the benchmark baseline, not a universal intelligence multiplier.
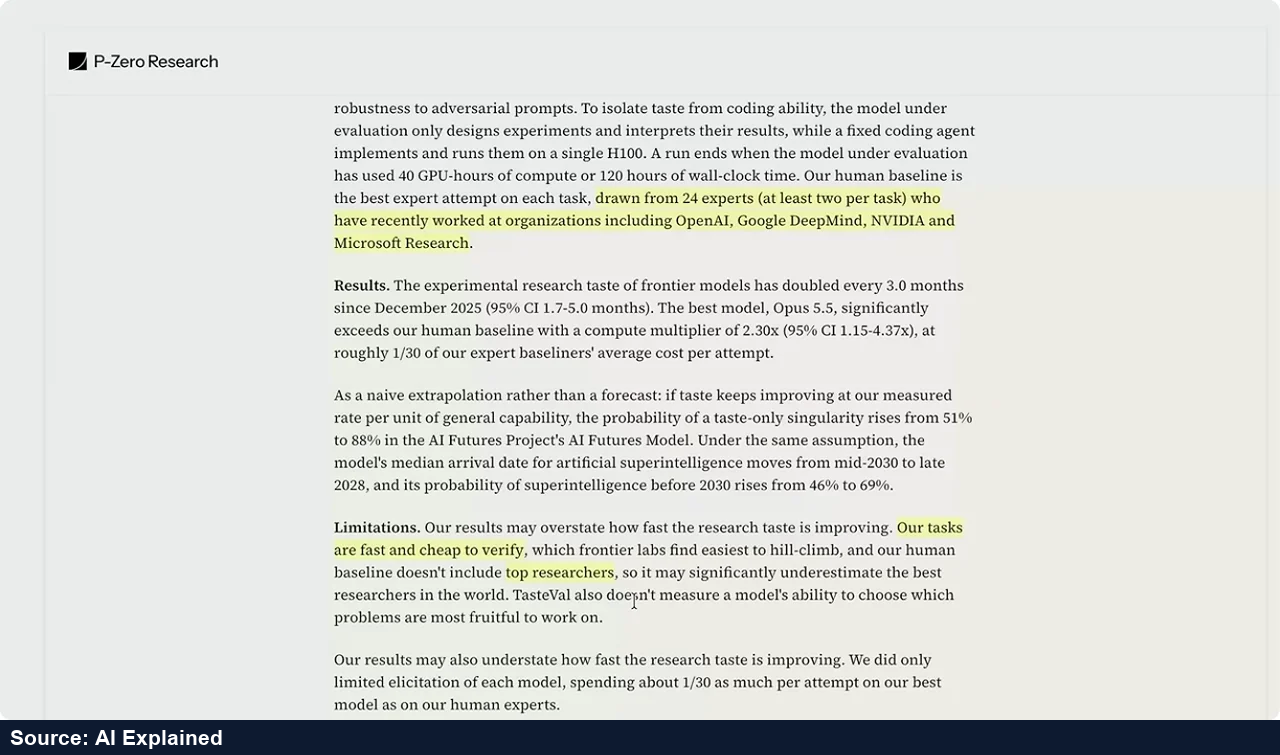
The authors’ explanation emphasizes that the problem is supplied in advance. The benchmark does not measure choosing the most fruitful problem. Tasks are relatively cheap to verify, and the baseline does not include the very best researchers. The authors call their long-range extrapolation an extrapolation, not a forecast.
That distinction changes the interpretation. A model may choose an efficient experiment once the goal and testing setup are fixed, while still struggling to decide what is worth studying. Conversely, missing that broader ability does not erase genuine progress on the narrower task. Both statements can be true.
Why feedback changes the difficulty
The video offers a useful comparison: clearly defined goals and rapid checks make iteration easier; costly experiments, delayed signals and ambiguous goals make it harder. “Research taste” can therefore mean several different skills, from selecting an experiment to choosing an entire research direction. One score should not stand in for all of them.
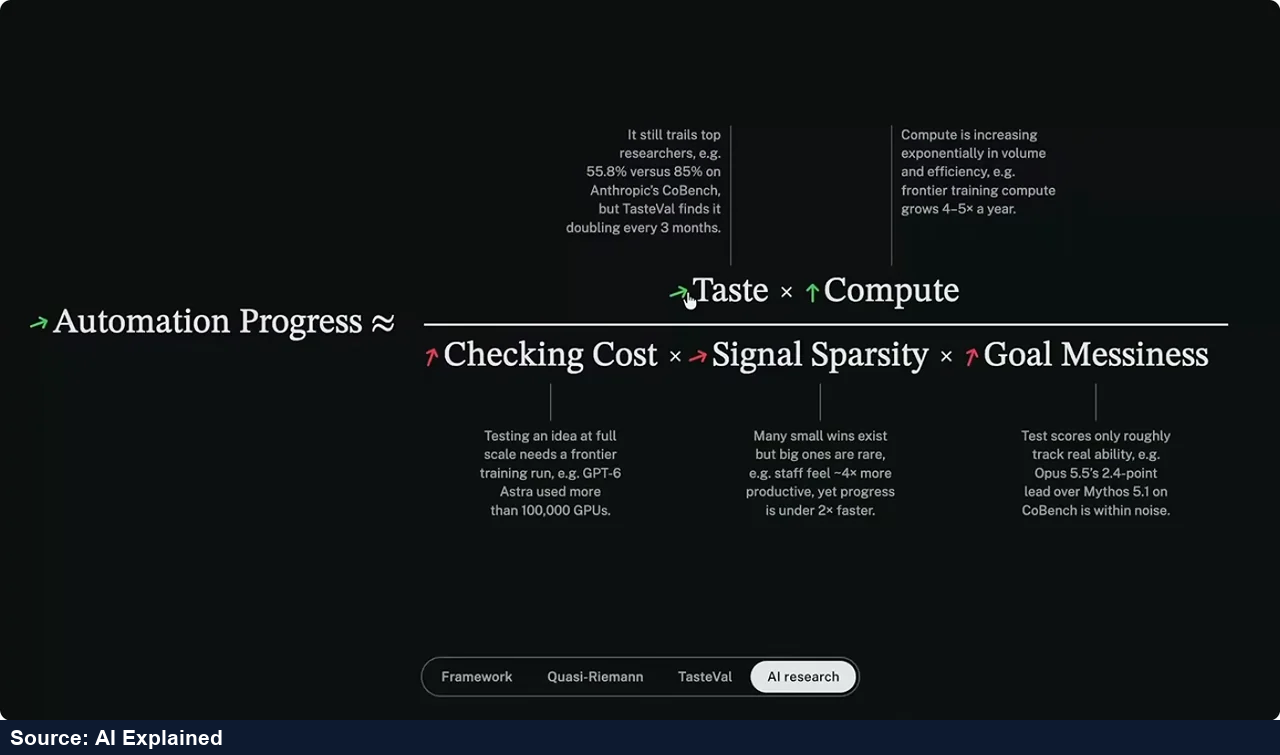
Imagine two hypothetical projects. In one, each proposed change can be tested in minutes against a fixed metric. In the other, deciding whether the experiment was worthwhile takes months and the target itself may change. The same number of attempts has a different meaning in those settings. This illustration explains the comparison; it is not additional experimental evidence.
A future date is still a forecast
In his 12 October newsletter, Jack Clark moves his expectation for full recursive self-improvement toward 2027 rather than 2028. It remains his judgment, not an achieved capability or a promised delivery date.
The video’s separate claim about an internal Codebench gap could not be independently checked here: the linked system card failed retrieval. We do not use that number as a verified result. Likewise, examples involving weather prediction, software reconstruction and fabrication are not treated as interchangeable proofs of general research ability.
For any future research headline, check the task, baseline, resource budget, uncertainty interval and verification method. Then ask what lies outside the test. That gives a more useful account of progress than either dismissing every result or declaring all scientific work solved.

